
Gemini 4 Carbon Overview
An overview of Gemini 4 Carbon: long-horizon coding, reasoning, cybersecurity, independent benchmarks, $2/$10 introductory pricing and public API access.
Published
Gemini 4 Carbon is the new Gemini 4 flagship announced by Google on 2026-10-28, with improvements in long-horizon coding, complex reasoning and cybersecurity defense. At launch, it ranked first on the Artificial Analysis Intelligence Index v5 with 59 points. On the independent Coding Agent Index, it placed second behind Claude Opus 5.5.
Google announced introductory pricing of $2 input / $10 output per million tokens, with $0.10 cached input. Initial access is through the Fairwind Program for selected trusted cyber defenders. A general opening date for developers, businesses and consumers has not been announced. At this check, APIMaster has no public Carbon route, so there is no APIMaster Carbon price or discount to quote.
For a Gemini API available today, compare Argon and 3.8 Flash. All prices below are USD per million input / output tokens; discounts use Google's current Standard introductory prices.
| Model ID | Official current / reference price | APIMaster current price | Active routes | Discount | Model card |
|---|---|---|---|---|---|
| Gemini 4 Carbon (public API ID unconfirmed) | Introductory $2 / $10; standard $4 / $20 | No public route | 0 | — | Check Carbon availability |
gemini-4-argon |
Currently $2 / $10; $4 / $20 from 2026-12-01 | From $0.834142 / $4.170712 | 4 | Up to ~58.3% off | Compare Argon routes |
gemini-3.8-flash |
Currently $0.75 / $3.75; $1.50 / $7.50 from 2027-01-01 | From $0.302013 / $1.510063 | 7 | Up to ~59.7% off | Compare Flash routes |
Checked 2026-10-31. Only public status=1 routes without client-exclusive labels are counted. Argon ranges from $0.834142–$2 input / $4.170712–$10 output; 3.8 Flash ranges from $0.302013–$1.50 / $1.510063–$7.50. The live marketplace card is authoritative. The Carbon link is an availability search, not confirmation of a callable Google API identifier.
GPT Trial(GPT-6 Astra, GPT-6 Sol, GPT-5.6, GPT-5.5, gpt-5.6-luna, gpt-5.6-sol, gpt-5.6-terra, gpt-6.1-sol, gpt-6-astra, gpt-6-sol, and gpt-6-luna available)
Sign up and claim a $20 GPT trial
Carbon's role: sustained work on complex engineering tasks
Carbon continues Argon's focus on long-horizon work: difficult bugs in large repositories, low-level systems, multistep engineering and security fixes that require repeated verification.
Google reports that internal teams have seen Carbon run for days, persist through dead ends, identify subtle bugs and produce patches. This is an internal usage report, not a promise that every public API request will execute continuously for days.
The practical question is whether the model can retain the goal, use tools to test its assumptions and recover after a failed approach. Repository maintenance, migrations and security work benefit from changes that can be accepted and verified.
According to Artificial Analysis, Carbon has a 1M-token context window, accepts text, image, video and speech input, and produces text. Video understanding does not establish video generation, and context capacity does not establish the maximum output length of one response.
Sources: Google announcement · Artificial Analysis evaluation.
Gemini 4 Carbon vs Argon: how much has improved?
Google's launch table shows gains across reasoning, long context, multimodal understanding and coding. The selected results below come from Google's published comparison, not APIMaster testing.
| Evaluation | Gemini 4 Carbon | Gemini 4 Argon | Change |
|---|---|---|---|
| AA Index v5.0, general capabilities | 59 | 50 | +9 index points |
| Vals Index v2.2, knowledge work | 70.4% | 69.2% | +1.2 percentage points |
| SWE-sweep, agentic coding | 9.6% | 4.3% | +5.3 percentage points |
| Terminal-Bench 4.0 (AA) | 65.2% | 57.1% | +8.1 percentage points |
| Agents' Last Exam v1.1, computer use | 77.4% | 69.0% | +8.4 percentage points |
| GraphWalks, 256K–1M BFS F1 | 96.2% | 84.2% | +12.0 percentage points |
| RiemannBench, mathematics | 80.0% | 76.0% | +4.0 percentage points |
The gains vary by task. GraphWalks and Terminal-Bench improve substantially; Vals Index moves more modestly. SWE-sweep more than doubles relative to Argon, but its absolute score is still 9.6%, leaving substantial room for progress on difficult coding work.
For web development, Google reports 1768 Elo, fourth place and an 89-Elo improvement on WebDev Arena. Actual selection should still check mobile layout, interactions and functional completeness.
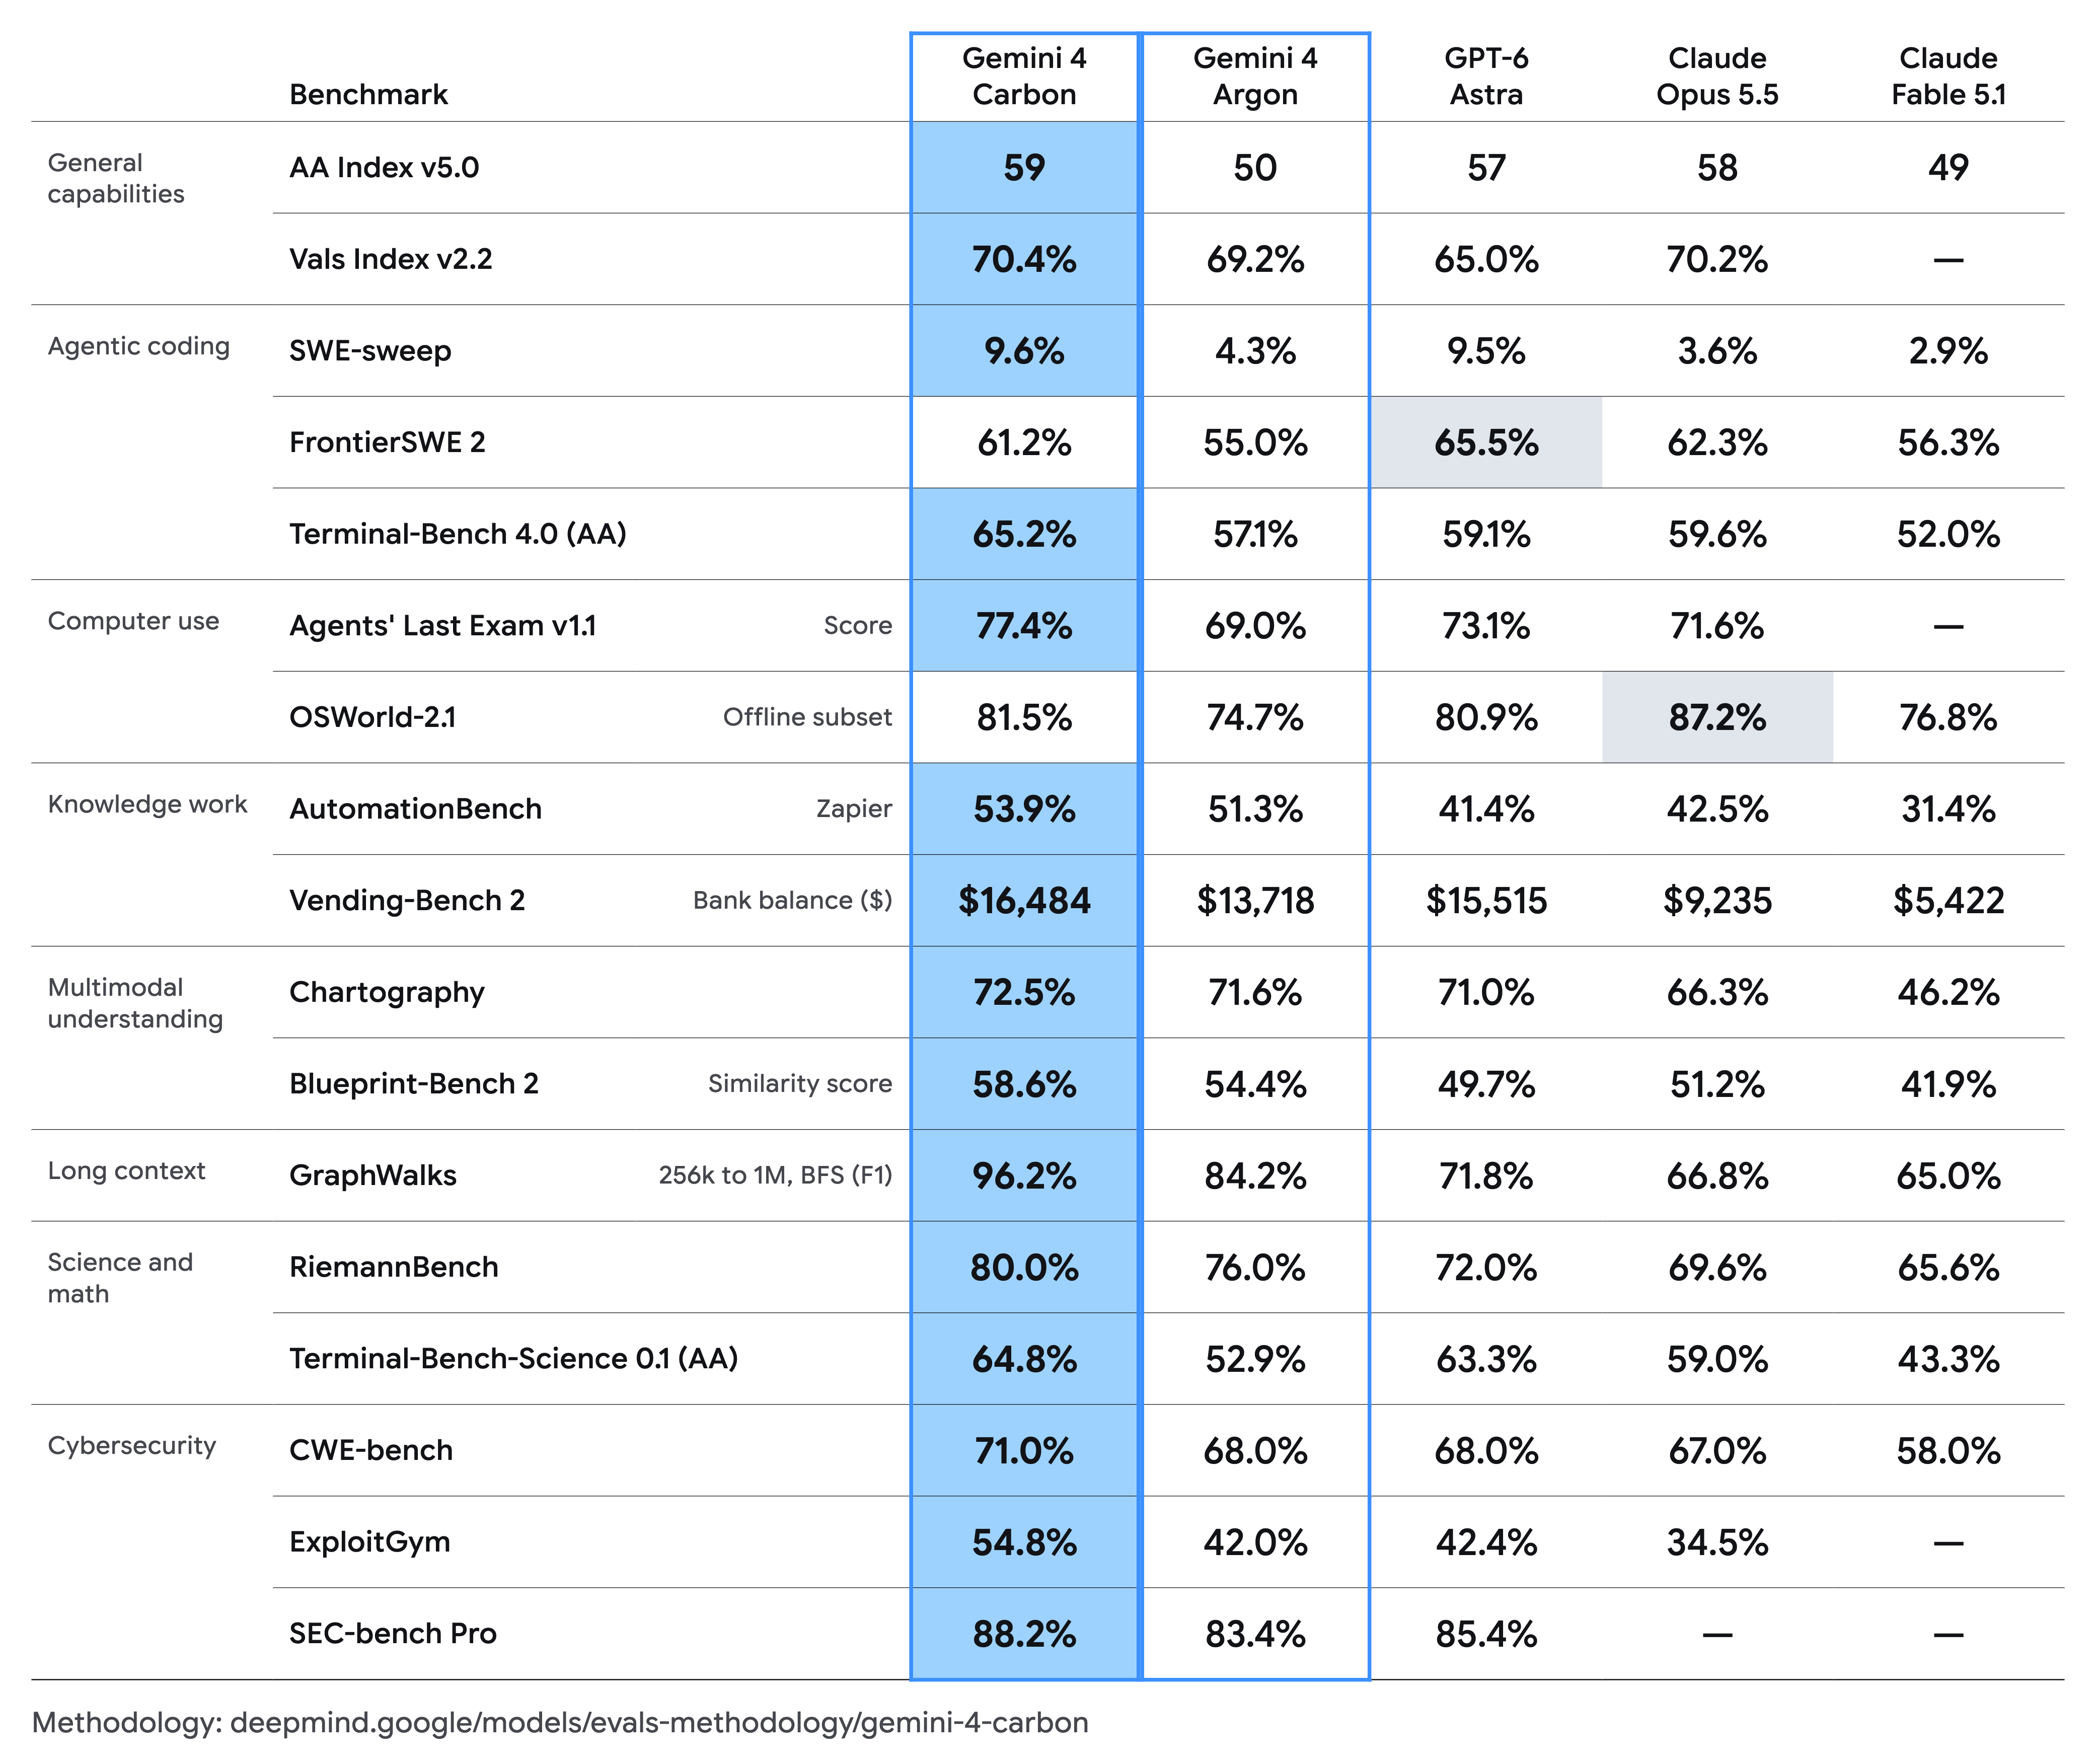
View Google's original evaluation table.
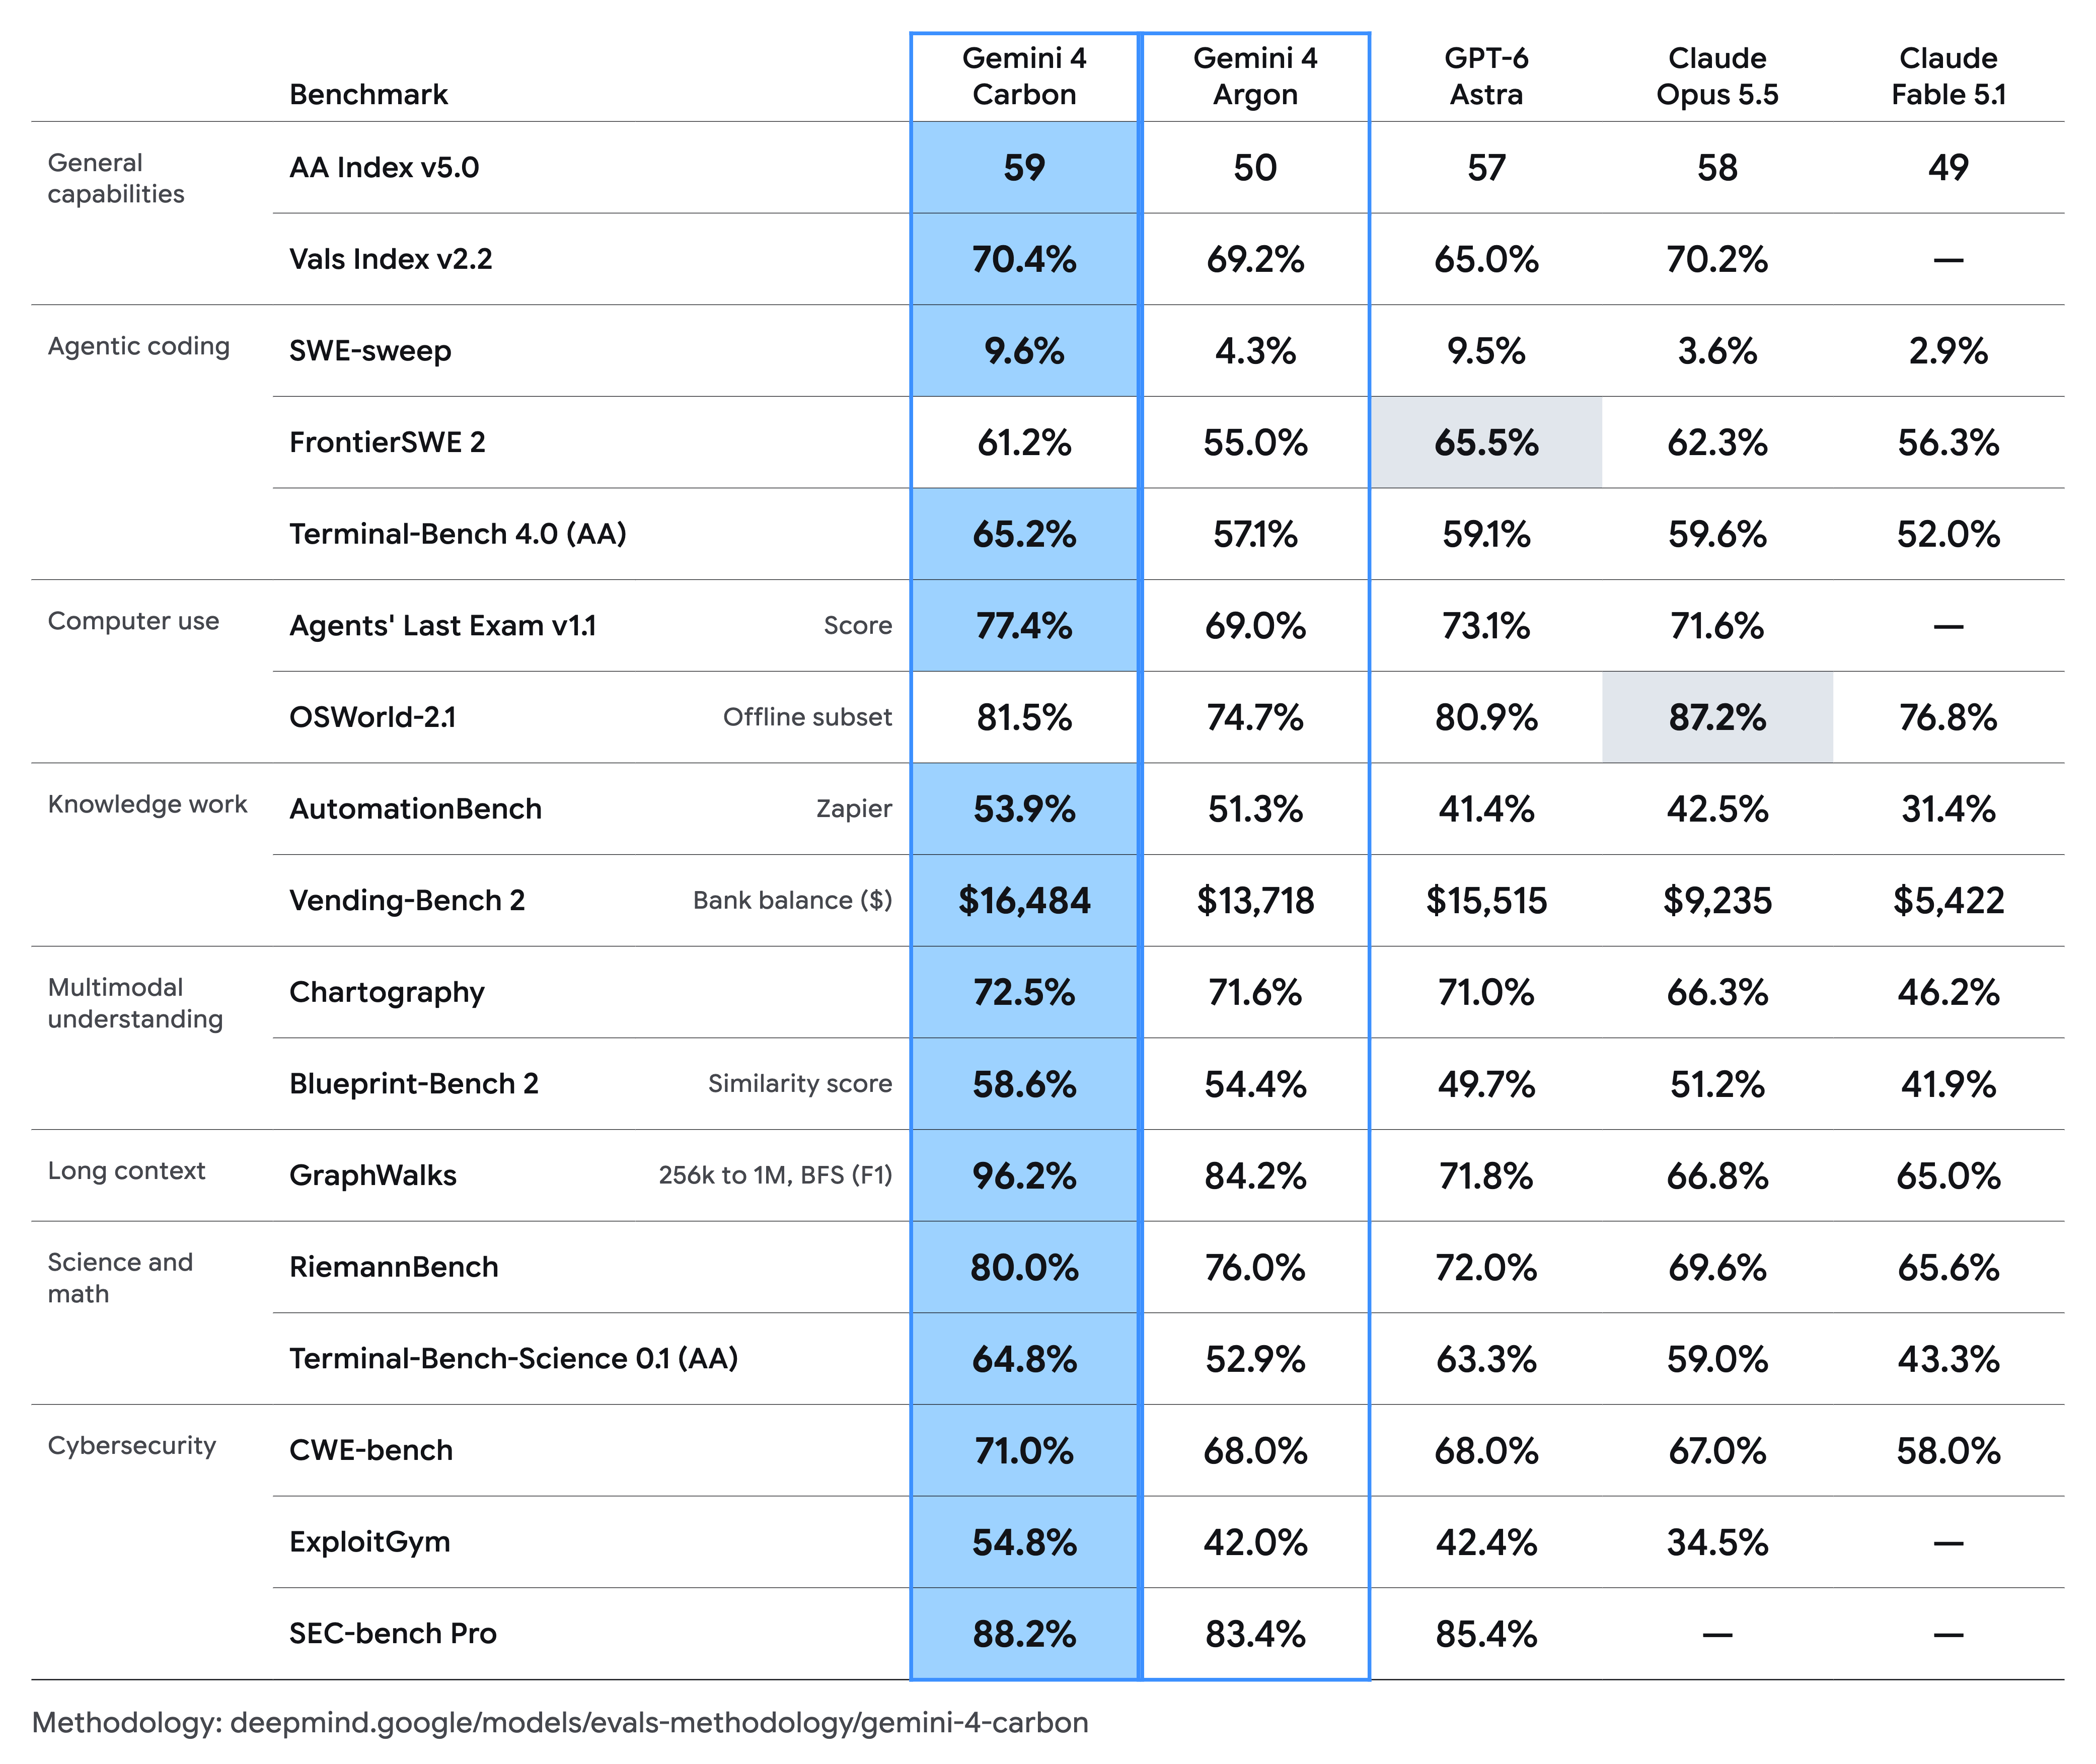
Does Carbon outperform Claude Opus 5.5 and GPT-6 Astra?
It led the AA general intelligence index at launch; task-specific results remain mixed. Google's table lists Carbon at 59, Opus 5.5 at 58 and GPT-6 Astra at 57. Artificial Analysis independently confirms Carbon's first place on Intelligence Index v5.
On the independent Coding Agent Index, however, Carbon with Antigravity CLI scores 59, behind Opus 5.5 with Claude Code at 62. This measures model-and-agent combinations, not a controlled experiment that swaps only the model.
Google's own launch table also includes areas where Carbon trails:
- FrontierSWE 2: Carbon scores 61.2%, below GPT-6 Astra at 65.5% and Opus 5.5 at 62.3%.
- OSWorld-2.1 offline subset: Carbon scores 81.5%, below Opus 5.5 at 87.2%.
For knowledge work, Artificial Analysis reports 1609 Elo on AA-Briefcase, up 126 from Argon, but still behind Kimi K3.1 Pro, Muse Wonder and Grok 4.7 in its evaluation.
Carbon is a strong general candidate; complex coding and knowledge work still deserve workload-specific comparisons. Evaluation settings also differ: Google's table reports Terminal-Bench at 65.2%, whereas the AA coding-agent article reports about 64%. Keep the original settings and attribution with each result.
Cybersecurity: finding, validating and patching vulnerabilities
Cyber defense is one of Carbon's clearest launch priorities. Google's three highlighted results cover successive steps of defensive work:
| Stage | Evaluation | Carbon | Argon |
|---|---|---|---|
| Find vulnerabilities | SEC-bench Pro | 88.2% | 83.4% |
| Validate exploitability | ExploitGym | 54.8% | 42.0% |
| Patch root causes | CWE-bench | 71.0% | 68.0% |
The workflow is to find a flaw, establish its risk and produce a fix. For maintainers, reducing false positives and delivering working patches can lower the cost of remediation.
Google also reports more than twice Argon's internal secure-code-generation success. The Chrome team's claim of over ten times better high-quality patch generation compares against an unnamed competing lab's model; it cannot be generalized to every coding task.
Google explicitly says the external cyber benchmarks were evaluated without guardrails. Public-product permissions, tools and safeguards may affect actual behavior.
Reliability on long tasks: fewer shortcuts and clearer evidence
Longer execution increases the cost of accumulated errors and deviation from the user's goal. Carbon's reliability work covers cheating, unsupported claims, overreach and incomplete execution.
Google reports 0.0% successful cheating and 0.4% attempted cheating on Terminal-Bench 4.0, with high-severity misalignment alerts down almost 80% in internal live coding environments. These findings concern the reported tests and environments, not an overall production incident rate.
Google says Carbon approximately halves unsupported claims relative to Argon, reduces overreach by 26% and under-service by 29%. When information is missing or sources conflict, it is more likely to retrieve evidence, surface the discrepancy and state what remains unfinished.
For prompt injection, Google reports that attack success on Gray Swan's indirect prompt-injection benchmark fell from Argon's 0.7% to 0.0%. Carbon resisted every evaluated attack in that run; this is not a guarantee of immunity to every prompt injection.
Independent testing adds nuance. On AA-Omniscience v1.1, Carbon's accuracy rises from Argon's 48% to 58%, while its hallucination rate under that benchmark's definition rises from 4% to 11%. Carbon remains among the lowest-hallucination models evaluated, but greater capability does not establish lower hallucination in every setting. Google's internal unsupported-claims test uses a different methodology.
Gemini 4 Carbon API pricing: introductory rates and task cost
Carbon's announced introductory rates are $2 input / $10 output per million tokens, a 50% discount from standard rates of $4 / $20. Cached input receives 95% off the applicable input rate: $0.10 during the introductory period and $0.20 at standard pricing. Carbon's own discount expiry date is unconfirmed; Argon's deadline should not be applied to it.
The caching discount applies only to qualifying cached input, not new input or output. It does not establish a particular KV-cache architecture, training-memory budget or hardware-utilization rate.
For a task using 100,000 input tokens and 20,000 billed output tokens, introductory pricing gives:
0.1 × $2 + 0.02 × $10 = $0.40
This fixed-token example excludes tools, retries and other charges. Long-running agents also incur intermediate reasoning, repeated reads and multiple execution steps. Compare the total cost of an accepted result.
Using standard pricing, Artificial Analysis reports $7.76 per Intelligence Index task for Carbon, versus $10.04 for Opus 5.5 and $6.25 for GPT-6 Astra. Cost advantages depend on the task and token consumption; an introductory token rate does not prove every task costs half as much.
Available same-family options are Argon and 3.8 Flash. At this check, their lowest public APIMaster routes are up to ~58.3% off and up to ~59.7% off Google's current Standard introductory prices. Choose for the workload, route capabilities and capacity; the marketplace card is authoritative.
Carbon and recursive self-improvement: what is confirmed?
Carbon arrived about two weeks after Argon's October 13 developer opening. That pace has prompted discussion of recursive self-improvement (RSI) and model-assisted AI research.
Google's Carbon announcement confirms that researchers and models are working together to advance capabilities and strengthen safeguards. It does not disclose enough of Carbon's training pipeline to verify use of a particular self-improvement paper, real-time training on user activity or autonomous upgrades without human involvement.
Model-assisted research is a useful direction to watch. Carbon's published evaluations, pricing and access terms are the evidence available for current selection decisions.
When will the Carbon API open, and is Carbon Gemini 4 Flash?
As checked on 2026-10-31, Google's announcement still describes a staged rollout: selected cyber defenders first, then more trusted Fairwind partners. It does not confirm a general date, final public API identifier, rate limits or subscription entitlements for ordinary developers, businesses and consumers.
Google has not identified Carbon as Gemini 4 Flash. Carbon's flagship positioning, announced price and first-access program do not establish the specifications of a future Flash product. Track their announcements separately.
For deployment today, use gemini-4-argon to establish a complex-task baseline, or gemini-3.8-flash for more cost-sensitive batch work. Once Carbon opens, compare the same inputs, tools and acceptance criteria: completion rate, human interventions, time and total cost.
Register with APIMaster → Create an API key → use API Base https://apimaster.ai/v1 with the currently available gemini-4-argon or gemini-3.8-flash. Check live prices and public routes on the Argon card and Flash card.
FAQ
Has Gemini 4 Carbon been released?
Google announced Carbon on 2026-10-28 with phased access for trusted cyber defenders. A general developer-availability date has not been announced.
Where does Carbon improve over Argon?
The launch table moves AA Index from 50 to 59, Terminal-Bench 4.0 from 57.1% to 65.2%, and GraphWalks from 84.2% to 96.2%. Long-horizon coding, complex reasoning and cybersecurity are major priorities.
Is Carbon the strongest coding model?
It improves on several coding evaluations, but the independent Coding Agent Index gives Carbon 59, behind Opus 5.5 with Claude Code at 62. Compare real tasks with fixed tools and budgets.
What does the Carbon API cost?
Announced introductory rates are $2 input / $10 output per million tokens, with $0.10 cached input. Standard rates are $4 / $20 and $0.20 cached input. Carbon's discount expiry date is unconfirmed.
Can I call Carbon on APIMaster now?
No public Carbon route was found at this check. Argon has 4 public active routes and 3.8 Flash has 7. A Carbon search link does not mean the model is listed for sale.
Is Carbon immune to prompt injection?
Google reports 0.0% attack success in a specific Gray Swan indirect prompt-injection evaluation. That result covers the evaluated attacks, not every possible attack.
Sources
- Google: Carbon announcement, 2026-10-28
- Google: original benchmark comparison
- Artificial Analysis: intelligence, coding agents, hallucination and task costs, 2026-10-28
- Google: official Gemini API pricing
- Google: Fairwind Program
- APIMaster: live Argon marketplace data · 3.8 Flash · Carbon availability