
Kimi K3.1 Pro API: Up to 70% Off, Pricing & Release Timeline
Kimi K3.1 Pro API from $0.60 input / $3 output per 1M tokens on APIMaster, up to 70% off official base rates. Explore 1M context, Highspeed and the release timeline.
Published · Updated
Kimi K3.1 Pro is released and available through Kimi, Kimi Work, Kimi Code and the official Kimi API. The official launch blog and API guide, checked on October 24, 2026, replace the earlier preview-only status. The accepted model IDs are kimi-k3.1-pro and kimi-k3.1-pro-highspeed.
Pro has a 1,048,576-token context window, text/image/video input, and text output. Official standard pricing is $2 input / $10 output per 1M tokens; Highspeed costs $4 / $20, with the same intelligence and 2–3× the speed, according to Kimi. Both list cached input at $0.20 / 1M tokens. Full model weights are planned by November 4, 2026; this is a future release commitment.
APIMaster price check: 2026-10-24. USD per 1M input / output tokens; only active public routes (status=1) are counted. Use the live marketplace card as the source of truth. Official prices and APIMaster quotes are separate:
| Model ID | Official reference | Current APIMaster price | Active routes | Discount | Model card |
|---|---|---|---|---|---|
kimi-k3.1-pro |
$2 / $10 | $0.60 / $3 – $2 / $10 | 2 | Up to 70% off | Check current quote |
kimi-k3.1-pro-highspeed |
$4 / $20 | No public route | 0 | — | Track Highspeed |
kimi-k3 |
$3 / $15 | $1.938 / $9.69 – $3 / $15 | 7 | Up to ~35% off | Compare K3 routes |
kimi-k2.7-code |
$0.95 / $4 | $0.7125 / $3 – $0.95 / $4 | 5 | Up to 25% off | Compare Code routes |
kimi-k2.6 |
$0.95 / $4 | $0.95 / $4 | 2 | No discount | View K2.6 |
Pro is now listed from $0.60 input / $3 output per 1M tokens, approximately 70% below Kimi's official $2 / $10 base rates. The two active public routes have different prices; check the current card and final quote. This is a marketplace availability and price check, without a paid Pro inference test.
GPT-kokeilu(GPT-6 Astra, GPT-6 Sol, GPT-5.6, GPT-5.5, gpt-5.6-luna, gpt-5.6-sol, gpt-5.6-terra, gpt-6.1-sol, gpt-6-astra, gpt-6-sol ja gpt-6-luna käytettävissä)
Rekisteröidy ja saat $20 GPT-kokeilun
Kimi K3.1 release date: from teaser to Pro launch
The Pro launch follows the October 23 official demonstration; by the October 24 check, the launch blog, model list and API guide confirm public availability. Earlier teaser dates describe earlier signals, not the date every account received access.
| Date (2026) | Event | What the evidence establishes |
|---|---|---|
| September 19 | Kimi's verified Zhihu account posts pi digits beginning 415926535897932.... |
The original tracker records an official-channel teaser; the community reads the missing 3.1 prefix as a hint. No specifications accompany it. |
| Late September | Developers reportedly find kimi-k3-1 on the API platform. |
A retrospective claim in ChainCatcher's October 23 report; the original response and exact discovery date were not independently verified. |
| October 16 update | This tracker archives lyra's report of internal K3.1 testing. | The article's update date is not a verified testing start date. |
| October 21 | K3.1 reportedly appears in Kimi Code's model-switch configuration. | An attributed configuration sighting, not proof of general API access at that time. |
| October 23 | Kimi publishes an official coding video. | A public demonstration; ChainCatcher describes a terminal labeled Model: Kimi K3.1 and Three.js scene generation. |
| October 23–24 launch rollout | Official launch materials introduce Pro and Pro Highspeed; checked October 24. | Current API documentation confirms kimi-k3.1-pro and kimi-k3.1-pro-highspeed, prices and access requirements. |
| By November 4 | Kimi plans to release full model weights. | A future commitment; API availability does not mean the checkpoint is already downloadable. |
The earlier internal-testing screenshot remains as historical context:
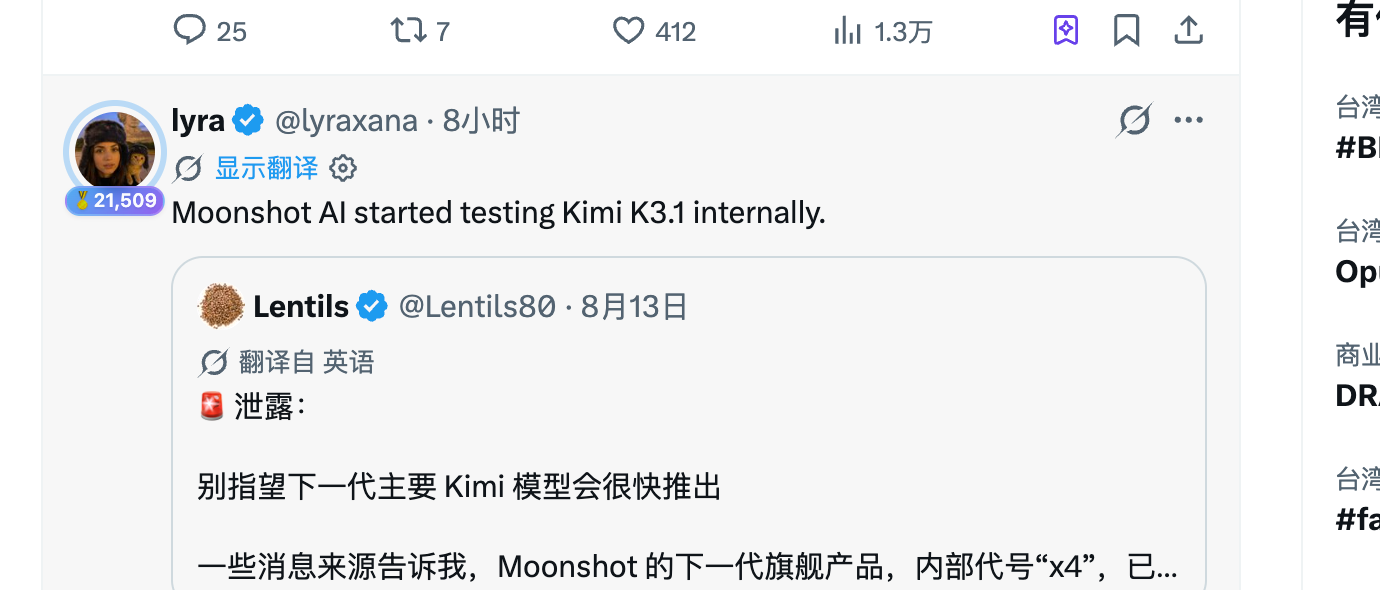
The embedded Lentils post in that screenshot is dated August 13. It is older discussion, not a separate Pro launch announcement.
Kimi K3.1 Pro specs: context, modalities and reasoning
Kimi describes Pro as the first model in the K3.1 series and a 3T-class model post-trained from Kimi K3, with substantially larger post-training compute. The documentation now supplies model-specific limits; these are no longer inferred from a short demo.
| Specification | Confirmed Kimi K3.1 Pro information |
|---|---|
| API ID | kimi-k3.1-pro |
| Highspeed API ID | kimi-k3.1-pro-highspeed |
| Context window | 1,048,576 tokens |
| Input / output | Text, images and video input; text output |
| Reasoning | Always enabled; reasoning_effort: low, high, max; default max |
| Completion budget | max_completion_tokens defaults to 131072; documented setting ceiling 1048576, subject to the remaining combined context |
| Developer features | Streaming, tool calls, structured output and context caching |
| Official API access | Successful top-up required, minimum $1; account tier determines rate limits |
| Weight release | Full weights planned by November 4, 2026 |
A 1M context is a shared request budget, not a promise of simultaneous 1M input plus 1M output. The exact output allowance also depends on the serving provider. The official model list calls Pro 3T-class; this article does not promote a separately unverified active-parameter count into a confirmed specification.
Kimi K3.1 Pro benchmarks: coding, 3D and finance
The following results come from Kimi's launch blog and its benchmark figures, not an APIMaster evaluation. Kimi says its Pro evaluations generally use reasoning_effort=max, temperature 1.0 and top-p 0.95 unless otherwise specified. Harnesses and evaluation setups differ by benchmark.
| Evaluation | K3.1 Pro | Comparison or interpretation |
|---|---|---|
| Terminal-Bench 4.0 | 65.7% | Kimi reports Opus 5.5 at 66.4% and GPT-6 Astra at 58.2%; Pro uses a Claude-Code harness. |
| Kimi Code Bench 3.0 Long-horizon | 61.2% | K3: 55.95%; Kimi's internal multi-step engineering benchmark. |
| BenchCAD, with tools | 92.7% | Opus 5.5: 96.2%; GPT-6 Astra: 95.9%. The figure specifies a 1,000-file subset and Voxel IoU. |
| OfficeQA Pro v2 | 64.4 | Financial-document retrieval, cross-document checks and multi-step numerical reasoning. |
| Frontier Finance | 58.6 | Reported in the official finance figure; measures investment workflows. |
| Kimi Hallu Bench Hard | 8.3% claim-level hallucination rate | K3: 23.4%; lower is better, on an internal stress test. |
The capabilities behind those results are concrete: full-project builds in Unity, Unreal Engine and Godot; parametric Blender and CAD modeling through scripts; and financial modeling with linked formulas and source-grounded research. Kimi's internal finance scores improve by 7.2 points for modeling and 11.6 points for research over K3.
The drop from 23.4% to 8.3% is approximately 65% relative reduction on that hallucination stress test. It is not a measured reduction in every user's daily error rate. Likewise, one strong coding score does not establish that Pro wins every task or consistently beats Opus.
Kimi K3.1 Pro vs Highspeed: what changes?
Kimi describes Highspeed as offering the same intelligence at 2–3× the speed. It charges twice the uncached-input and output rates, while cached-input pricing is the same.
| Item | Pro | Pro Highspeed |
|---|---|---|
| Model ID | kimi-k3.1-pro |
kimi-k3.1-pro-highspeed |
| Context | 1,048,576 tokens | 1,048,576 tokens |
| Official input / output per 1M | $2 / $10 | $4 / $20 |
| Official cached input per 1M | $0.20 | $0.20 |
| Speed | Standard | Kimi claims 2–3× Pro; no fixed TPS guarantee |
| APIMaster public route count on October 24 | 2 | 0 |
For batch analysis and long coding jobs, Pro's lower token rates may matter more. For interactive agents, Highspeed may reduce waiting time, but compare time to first token, completed-task latency and total tokens on your own workload. A relative speed claim is not a universal tokens-per-second guarantee.
K3.1 Pro is also distinct from the older K2.8 Preview and its kimi-for-coding access surface. In Kimi Code, use /model and select the released Pro model rather than assuming an old alias maps to it.
Kimi K3.1 Pro API pricing: input, output and caching
The official pricing page lists the following USD rates per 1M tokens, excluding applicable taxes. Kimi's billing FAQ says Pro uses flat token rates, with no context-length price tiers.
| Official model | Input, cache miss | Output | Cached input | Cache write, 5m TTL | Cache write, 1h TTL |
|---|---|---|---|---|---|
kimi-k3.1-pro |
$2.00 | $10.00 | $0.20 | $2.00 | $4.00 |
kimi-k3.1-pro-highspeed |
$4.00 | $20.00 | $0.20 | $4.00 | $8.00 |
kimi-k3 |
$3.00 | $15.00 | $0.30 | $3.00 | $6.00 |
Pro's standard input and output rates are each 33.3% below K3's official rates. For illustration, 100,000 input tokens plus 10,000 output tokens at the base non-cached rates cost $0.30 on Pro, $0.60 on Highspeed and $0.45 on K3. This arithmetic excludes any separate cache-write items, external tools, taxes and repeated agent calls.
Kimi automatically enables context caching for repeated prefixes, with a default 5-minute TTL. Cache writes are separate billing items; cached input uses the cache-hit rate. Check usage details and TTL settings rather than estimating a long agent run from prompt size alone.
Official API pricing is separate from a Kimi app or Kimi Code subscription. The API guide requires a successful top-up of at least $1 to unlock the flagship model; rate limits depend on the account tier.
APIMaster Kimi prices: compare the current route before buying
The new Pro market card currently lists 2 active public routes from $0.60 / $3 to $2 / $10 per 1M input / output tokens. The Highspeed card has 0. These October 24 marketplace results supersede the earlier “no K3.1 routes” statement.
The lowest Pro route offers up to 70% off the official input and output rates. This compares base token rates; cache writes, tool charges and provider-specific limits require their own checks. We have not run a paid Pro request for this article.
For existing-model workloads, Kimi K3 has 7 active routes, ranging from $1.938 / $9.69 to $3 / $15, or up to approximately 35% off official K3 pricing. K2.7 Code has 5 routes from $0.7125 / $3 to $0.95 / $4, up to 25% off. K2.6 has 2 routes at $0.95 / $4, with no discount.
These are different models with their own route prices. Compare Pro with its own official $2 / $10 baseline, and K3 with $3 / $15. Kimi also states that K2-series models will close to new users on October 31, with retirement planned by the end of December 2026; that is Kimi's official platform schedule, not a verified APIMaster shutdown date.
How to use the Kimi K3.1 Pro API
The official quickstart uses an OpenAI-compatible client and the Moonshot endpoint. Install the OpenAI SDK, set your own MOONSHOT_API_KEY, and use the exact released model ID:
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["MOONSHOT_API_KEY"],
    base_url="https://api.moonshot.ai/v1",
)

response = client.chat.completions.create(
    model="kimi-k3.1-pro",
    reasoning_effort="high",
    max_completion_tokens=4096,
    messages=[
        {"role": "user", "content": "Write a Python function to validate an IPv4 address."}
    ],
)
print(response.choices[0].message.content)
To use the official high-speed variant, change the model to kimi-k3.1-pro-highspeed. Pro always has thinking enabled; choose low, high or max to tune effort. In multi-turn or tool-call workflows, preserve the complete assistant message, including reasoning fields returned by the service, in the following request as documented.
For APIMaster, use an APIMaster key, base URL https://apimaster.ai/v1, and a model listed on the chosen live card. Confirm the Pro price before changing a production client; kimi-k3 remains a separate available model. Earlier sightings such as kimi-k3-1 and kimi-k3.1 are historical identifiers, not substitutes for the documented kimi-k3.1-pro.
FAQ
Is Kimi K3.1 Pro released, and when?
Yes. The October 23 official video was followed by the Pro launch rollout, and the official blog and API documentation checked on October 24, 2026 confirm Pro and Highspeed availability across Kimi, Work, Code and the API. This supersedes the earlier preview-only status.
What is the Kimi K3.1 Pro API price?
Official Pro rates are $2 input / $10 output per 1M tokens, with $0.20 cached input. Highspeed is $4 / $20, also with $0.20 cached input. Cache writes have separate TTL-based rates. The official rate is not the same as an APIMaster route quote.
What are the exact API model IDs?
Use kimi-k3.1-pro or kimi-k3.1-pro-highspeed on the documented official endpoint. The earlier reported kimi-k3-1 and tracking label kimi-k3.1 are not the released IDs listed by Kimi.
Is Kimi K3.1 Pro open weight already?
Kimi describes Pro as an open-weight model and commits to releasing the full weights by November 4, 2026. At this October 24 check, that is a planned checkpoint release; API availability alone does not establish a downloadable checkpoint or its final license.
How is Highspeed different from Pro?
Kimi says it has the same intelligence and runs 2–3× faster. Its uncached-input and output prices are twice Pro's, while cached input remains $0.20 per 1M tokens. APIMaster has no public Highspeed route in this check.
Can I use Kimi K3.1 Pro through APIMaster now?
The marketplace returns 2 active public Pro routes on October 24, from $0.60 input / $3 output to $2 / $10 per 1M tokens. The lowest is approximately 70% below the official base rates. No paid request was tested for this article; check the live card and final quote. Highspeed has no active public route in this check.
Sources and verification date
- Kimi K3.1 Pro launch blog: official availability, capabilities, benchmark values and conditions, Highspeed speed claim, and November 4 weight-release commitment; checked October 24, 2026.
- Kimi K3.1 Pro API quickstart: model IDs, access requirements, reasoning controls, multimodal input and completion settings.
- Official model list, token pricing, account and billing, and context caching: model availability, prices, cache-write billing and migration notes.
- October 23 official video: earlier public demonstration. ChainCatcher's October 23 report supplies the attributed late-September and October 21 sightings; original API/configuration records were not independently verified.
- lyra (@lyraxana) and Kimi's verified Zhihu account: historical internal-testing screenshot and September 19 teaser retained from this tracker.
- Kimi Code model documentation: product-specific model selection.
- APIMaster public marketplace API, checked 2026-10-24, for
kimi-k3.1-pro,kimi-k3.1-pro-highspeed,kimi-k3,kimi-k2.7-codeandkimi-k2.6; only active public routes counted. Route availability and prices are a timestamped snapshot.
Choose a Kimi API route with a clear price
The newly released Kimi K3.1 Pro starts at $0.60 / $3, approximately 70% below its official $2 / $10 base rates in this check. The older K3 card starts at $1.938 / $9.69; choose the model and route for your workload.
Register with APIMaster, create an API key in the console, and configure https://apimaster.ai/v1 with your chosen documented model ID. Use kimi-k3 for the K3 route; select kimi-k3.1-pro only after reviewing its current price and supported limits.